LLM eval harness: catch a worse prompt before it ships
An eval harness for a Claude support-ticket triage feature: a 20-case golden dataset, exact-match and LLM-as-judge graders, the cost of each run, and a CI gate that fails the PR when quality drops.
src/eval.ts + eval.yml, the 5 tests passing and the regressed replay failing the gate (exit 1). No audio; captions on screen.The problem it solves
A prompt change that looks better on three examples can quietly break the cases that matter. Without a test, the first person to notice is a customer whose urgent ticket was filed as normal.
This harness turns that into a red build. It runs the feature over a golden dataset, grades exact fields exactly and only uses an LLM judge for free text, reports the pass rate, per-field accuracy and the cost of the run, then fails the PR if the pass rate drops more than a tolerance below the baseline, or if any single urgent ticket is missed, whatever the average says.
How it fits together
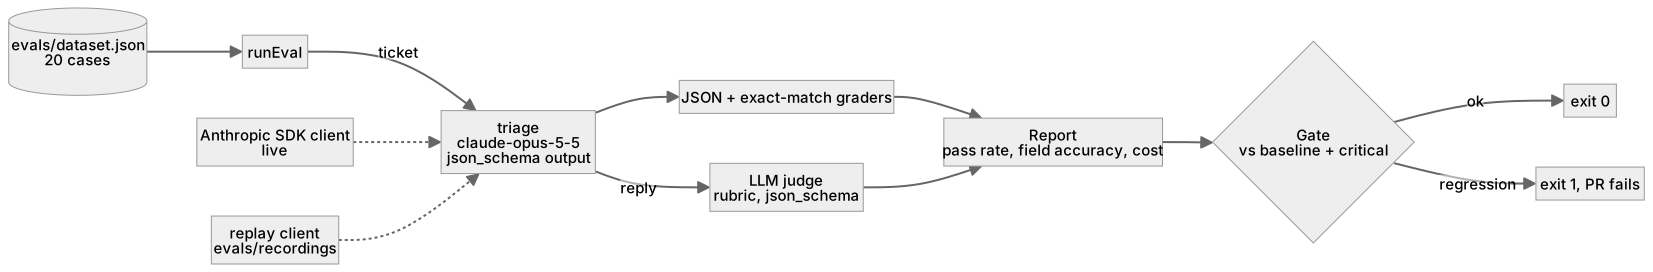
| Grader | Checks |
|---|---|
| JSON | the output parses (a broken response fails the case instead of crashing the run) |
| Exact match | category, priority, order_id |
| LLM-as-judge | the free-text reply against a rubric: polite, on-topic, no promised refunds, amounts or dates, under 80 words |
The GitHub Actions workflow runs the tests and the gate on every push and PR, and also runs the regressed recording to prove the gate still bites.
The key code
The gate in src/eval.ts and the CI steps in .github/workflows/eval.yml.
/** The CI gate: fail on a pass-rate drop beyond tolerance, or on any critical miss. */
export function gate(report: Report, baseline: Baseline): { ok: boolean; reasons: string[] } {
  const reasons: string[] = [];
  const floor = baseline.passRate - baseline.tolerance;
  if (report.passRate < floor) reasons.push(`pass rate ${pct(report.passRate)} is below ${pct(floor)} (baseline ${pct(baseline.passRate)} - ${pct(baseline.tolerance)})`);
  for (const f of report.failures.filter((f) => f.critical)) reasons.push(`critical: ${f.id} is urgent but was not flagged urgent`);
  return { ok: reasons.length === 0, reasons };
}

# .github/workflows/eval.yml (steps)
      - run: npm ci
      - run: npm run typecheck
      - run: npm test
      # The gate: exits 1 (and fails the PR) when quality drops. Summary lands on the job page.
      - run: npm run eval
      # Proof the gate bites: the regressed recording must fail it.
      - run: "! npm run eval -- regressed"
src/eval.ts lines 73–80 and the last steps of eval.yml. The ! step fails CI if the regressed recording ever stops failing the gate.Proof: the real test run
Run on 16 Oct 2026 on the published commit: npm test, then npm run eval -- regressed, which exited with code 1 as designed. Both run offline from the recordings.
✔ baseline recording: 19/20 pass and the gate is green
✔ regressed recording: the gate fails and names every broken case
✔ each grader catches its own kind of failure
✔ a single critical miss fails the gate even when the pass rate is fine
✔ cost is summed from usage on every triage and judge call
ℹ tests 5
ℹ pass 5
ℹ fail 0
npm test: 5 tests, 5 pass, 0 fail.## Eval: replay of recordings/regressed.json FAIL
14/20 cases passed (70%) on claude-opus-5-5, cost $0.1221
| field | accuracy |
|---|---|
| json | 95% |
| category | 90% |
| priority | 85% |
| order_id | 90% |
| reply | 90% |
Failed cases:
- t04 (critical): priority: got "normal"
- t08: order_id: got "0988"
- t10: reply: Promises a specific refund amount and timing the agent cannot guarantee.
- t12: not JSON: Sure! Here is the triage: category technical
- t14 (critical): priority: got "normal"
- t15: category: got "other"
Gate:
- pass rate 70% is below 90% (baseline 95% - 5%)
- critical: t04 is urgent but was not flagged urgent
- critical: t14 is urgent but was not flagged urgentnpm run eval -- regressed: 14/20, two urgent tickets missed, gate FAIL, exit code 1.Choices and limits
- Exact match where the answer is exact, a judge only for free text. Judges cost money and drift; categories and ids don't need one.
- Critical cases gate on their own, because averages hide the failure that hurts a customer most.
- 20 cases is a smoke test, not a benchmark; a real project grows the set from production tickets.
- The judge itself is not evaluated here; a real setup checks it against human-labelled replies first.
- Cost in replay mode is computed from recorded token counts at Opus 5.5 prices, so it is an estimate, not a bill.
Code
Code, README, tests and CI: github.com/mcknx/llm-eval-harness (MIT).
Honest note: a demo project with fictional data, not client work. The 20 support tickets are fictional, and the two recordings are synthetic: hand-written stand-ins for model outputs (one good, one with typical regressions), so the harness and its CI gate run offline and free. npm run eval -- live runs it against the real API with a key; no live results are claimed here.
More like this: Claude agent loop guard · SaaS billing starter