Claude agent loop guard: an AI agent that cannot loop forever or overspend
A Claude tool-use agent that browses a shop with Playwright, wrapped in the guards that stop it looping or burning money: max turns, a USD budget, a repeat-call breaker, checkpoint/resume and a per-call cost log.
src/agent.ts, the 6 tests passing and an npm start run. No audio; captions on screen.The problem it solves
An agent that calls tools in a loop can get stuck: it asks for the same page again and again, or keeps going long after it has the answer, and every turn is a paid API call. Nobody notices until the bill arrives.
This repo shows the fix in code an employer can read in a few minutes: check the turn and dollar ceilings before each call, recognise a repeated tool call by a canonical key (argument order ignored), answer the first repeat with a cheap error instead of re-running the tool, stop hard at a small threshold, and write a checkpoint after every turn so a stopped run resumes without fetching anything twice.
How it fits together
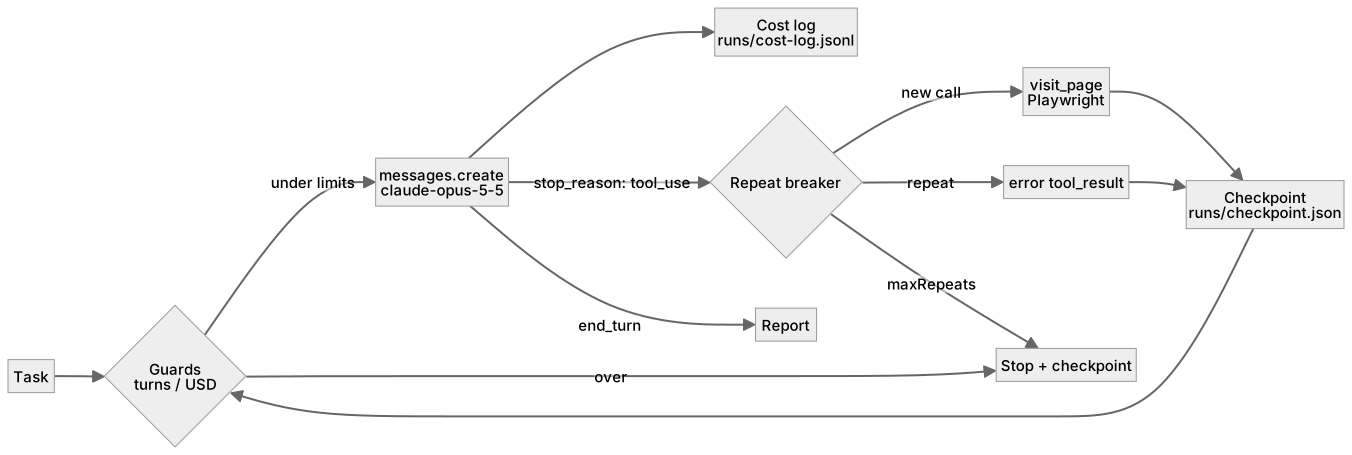
| Guard | What trips it | What happens |
|---|---|---|
| Max turns | turns >= maxTurns | stops before paying for the next call |
| USD budget | spent >= maxUsd, priced from usage on every response | stops before the next call |
| Repeat breaker | same tool + same arguments again | 2nd time the tool is not re-run, the model gets an error result; at maxRepeats a hard stop |
| Checkpoint / resume | written after every turn | a stopped or crashed run continues from the file |
| Cost log | every model call | one JSON line: tokens in/out, call cost, running total |
The key code
The heart of src/agent.ts: the guards run before the paid call, every call is priced and logged, and a repeated tool call gets a soft brake before the hard stop.
while (true) {
  // Guards run BEFORE spending money on the next call.
  if (cp.turns >= limits.maxTurns) return end("max_turns");
  if (cp.usd >= limits.maxUsd) return end("budget");

  const res = await client.messages.create({
    model,
    max_tokens: 16000,
    system: opts.system,
    output_config: { effort: "low" }, // simple browsing task: fewer, consolidated tool calls
    tools: tools.map(({ run: _run, ...def }) => def),
    messages: cp.messages,
  });
  cp.turns++;
  const usd = costUsd(res.usage);
  cp.usd += usd;
  fs.appendFileSync(
    opts.costLogPath,
    JSON.stringify({ turn: cp.turns, in: res.usage.input_tokens, out: res.usage.output_tokens, usd, totalUsd: cp.usd, stop: res.stop_reason }) + "\n",
  );
  // Append the full content (thinking blocks included) so the history stays valid.
  cp.messages.push({ role: "assistant", content: res.content });

  const text = res.content.flatMap((b) => (b.type === "text" ? [b.text] : [])).join("\n");
  if (res.stop_reason === "refusal") return end("refusal", text);
  if (res.stop_reason === "max_tokens") return end("max_tokens", text);
  if (res.stop_reason !== "tool_use") return end("done", text);

  const results: Anthropic.ToolResultBlockParam[] = [];
  let looping = false;
  for (const b of res.content) {
    if (b.type !== "tool_use") continue;
    const key = callKey(b.name, b.input);
    const seen = (cp.calls[key] = (cp.calls[key] ?? 0) + 1);
    if (seen >= limits.maxRepeats) looping = true;
    // ...unknown-tool and tool-error handling...
    results.push({ type: "tool_result", tool_use_id: b.id, content, is_error });
  }
  // Every tool_result goes back in ONE user message (keeps parallel tool use working).
  cp.messages.push({ role: "user", content: results });
  save();
  if (looping) return end("loop", text); // hard stop: same call hit maxRepeats
src/agent.ts lines 63–121 (the unknown-tool and tool-error branches are shortened here; the full file is in the repo).Proof: the real test run
Run on 16 Oct 2026 on the published commit: npm test (no API key, no network beyond the local fixture site) and npm start. The happy-path test drives a real headless Chromium through the fixture shop.
✔ happy path: real Playwright over the fixture site, scripted model
✔ max turns guard stops a model that never finishes
✔ USD budget guard stops before the next call once spend hits the ceiling
✔ repeat breaker: soft warning on the 2nd identical call, hard stop on the 3rd
✔ checkpoint/resume: a stopped run continues where it left off without redoing work
✔ cost log: one JSON line per model call, totals match the result
ℹ tests 6
ℹ pass 6
ℹ fail 0
npm test: 6 tests, 6 pass, 0 fail.Model: scripted fake (no ANTHROPIC_API_KEY set)
stop=done turns=3 usd=$0.0240
| Product | Price | Weight | Rating |
|---|---|---|---|
| Summit 40 | $129.00 | 1.4 kg | 4.8 |
| Ridge 35 | $89.00 | 1.1 kg | 4.6 |
| Daylite 20 | $49.00 | 0.6 kg | 4.1 |
Best value: Ridge 35 (4.6 rating at $89).npm start without a key: the scripted model drives real Playwright over the fictional shop and stops after 3 turns.Choices and limits
- A manual loop on the Anthropic SDK, not the Claude Agent SDK. For a custom-tool agent that owns every guard, the plain Messages API loop is smaller and easier to test.
- Prices are hard-coded for
claude-opus-5-5($4 / $20 per 1M tokens); changePRICEfor another model. - The budget is checked between calls, so one call can overshoot it. A per-call ceiling would size
max_tokensfrom the remaining budget. - Token counts from the fake model are fixed numbers, not real usage.
- Refusals and
max_tokensstops end the run; there is no model fallback.
Code
Code, README, tests and CI: github.com/mcknx/claude-agent-loop-guard (MIT).
Honest note: a demo project with fictional data, not client work. The shop is a local fixture. No API key was used for the output above: the loop ran against a scripted fake model client; the browser part is real Playwright. With ANTHROPIC_API_KEY set, the same loop calls the real API.
More like this: SaaS billing starter · LLM eval harness